When Americans cast ballots in a midterm election, the act of voting is only the opening movement of a longer civic performance. The decisive moment that audiences actually watch for is not the closing of the polls but the instant a network, wire service, or newspaper declares that a particular race has been won. That declaration is never a casual observation; it is the product of an elaborate institutional machinery built over decades, combining raw vote tallies, statistical sampling, historical baselines, and layers of human judgment. Understanding how these calls are made reveals as much about the architecture of American democracy as it does about the craft of journalism.
The competitive dimension is impossible to ignore. Newsrooms race one another to be first, because a projected winner carries prestige, traffic, and the implicit claim of superior data operations. Yet that race is constrained by an equally powerful fear: calling a race prematurely and getting it wrong inflicts reputational damage that can linger for years. The result is a peculiar discipline in which speed is pursued relentlessly but never at the cost of the analytical safeguards that protect credibility. Outlets publish detailed methodologies precisely because their authority to declare winners rests on public trust rather than any legal mandate.
This analysis examines the full anatomy of that process, from the vote-counting infrastructure that feeds the decision desks to the statistical models that translate partial returns into probabilistic forecasts. It considers the role of exit polls, the geography of reporting precincts, the language of projection versus declaration, and the ethical boundaries that separate journalism from speculation. Along the way, it situates the American practice within a broader international context, where the authority to announce results is often vested in electoral commissions rather than newsrooms.
On This Page
- The Institutional Architecture Behind a Race Call
- The Data Streams That Feed a Projection
- The Statistical Logic of Calling a Race
- The Competitive Pressure and Its Discontents
- Projection Versus Certification: A Crucial Distinction
- Technology, Speed, and the Future of Race Calling
- What the Machinery Reveals About Democracy
TL;DR American news organizations do not simply report vote totals; they operate decision desks that synthesize precinct-level returns, exit polling, historical voting patterns, and statistical modeling to determine when a race can responsibly be called. The process is governed by a tension between competitive speed and institutional caution, with networks and the Associated Press maintaining independent methodologies, rigorous checks, and public explanations of their calls. Understanding this machinery clarifies why projections sometimes arrive minutes after polls close and sometimes take days, and why the distinction between a projection and an official certification matters enormously for public confidence in electoral outcomes.
The Institutional Architecture Behind a Race Call
At the center of the American election-night ritual sits an entity most viewers never see: the decision desk. This is a dedicated team of analysts, statisticians, and editors who work apart from the on-air anchors and correspondents, insulated from the pressure of broadcast deadlines so they can evaluate returns without theatrical interference. The Associated Press operates the most widely relied-upon desk, supplying race calls to thousands of member outlets, while major broadcast and cable networks maintain their own parallel operations. Each desk functions as a kind of analytical court, weighing evidence before issuing a verdict that carries enormous public consequence.
The separation between the decision desk and the newsroom is deliberate and structural. Analysts are typically forbidden from discussing pending calls with producers or anchors, a firewall designed to prevent ratings considerations from contaminating statistical judgment. This organizational design reflects a hard-won lesson from past failures, when premature or erroneous calls damaged public trust. By institutionalizing distance between the people who analyze and the people who broadcast, outlets attempt to ensure that the declaration of a winner reflects the evidence rather than the appetite for a dramatic moment.
Who Actually Makes the Call
The Associated Press has called American elections since 1848, making it the longest-standing such operation in the world. Its race callers work from a centralized Washington headquarters, drawing on a national network of stringers who report vote totals directly from county election offices. This ground-level reporting is laborious and unglamorous, but it gives the AP an independent data stream that does not depend on official websites or third-party aggregators. The cooperative's nonprofit structure and its reliance on member subscriptions rather than advertising revenue are frequently cited as reasons its calls are treated as a neutral benchmark.
Broadcast networks such as NBC, ABC, and CBS, along with cable operations and major newspapers, maintain their own decision desks, often staffed by veterans of polling firms and political consultancies. These desks may license data from the AP or gather returns independently, and they frequently reach the same conclusion within minutes of one another. The near-simultaneity of calls across outlets is not collusion but convergence: independent analysts examining the same underlying vote patterns will often arrive at the same threshold of certainty at roughly the same time, which itself reinforces public confidence in the result.
The Firewall Between Analysis and Broadcast
Inside a network, the decision desk operates under strict protocols that govern communication. Analysts may not preview calls to anchors, and producers cannot request that a call be accelerated to fit a broadcast window. When a call is ready, it is transmitted simultaneously to the graphics team, the anchor's teleprompter, and the network's digital properties, ensuring that no one receives advance notice that could be exploited. This simultaneity is both an ethical safeguard and a practical one, preventing leaks that would undermine the authority of the announcement.
The firewall extends to the language used on air. Anchors are trained to distinguish between a projection, which is a journalistic judgment based on available evidence, and a certification, which is the formal act of a state canvassing board or secretary of state. Confusing the two is treated as a serious error. This linguistic discipline matters because projections, however well-founded, are not legally binding, and the gap between a projected winner and a certified one can become the focus of litigation, recounts, or political contestation in close races.
The Data Streams That Feed a Projection
Every race call rests on a foundation of data that arrives in overlapping waves throughout election night. The first wave consists of raw vote counts, transmitted from thousands of county and municipal election offices as ballots are tabulated. The second wave comprises exit polls, conducted by interviewing voters as they leave polling places, which provide early signals about the composition of the electorate and the preferences of key demographic groups. The third wave is historical and contextual: registration data, turnout patterns, and the partisan lean of each precinct, which allow analysts to interpret partial returns against a known baseline.
None of these streams is sufficient on its own, and each carries characteristic weaknesses. Raw counts arrive unevenly, with urban precincts often reporting later than rural ones, creating temporary distortions in the aggregate. Exit polls, once a dominant tool, have been supplemented and partly supplanted by pre-election surveys and voter-file modeling after high-profile misestimations in earlier cycles. Historical baselines, meanwhile, can mislead when the political environment shifts sharply. The art of the decision desk lies in triangulating across all three streams, weighting each according to its reliability in a given contest.
Vote Counts and the Geography of Reporting
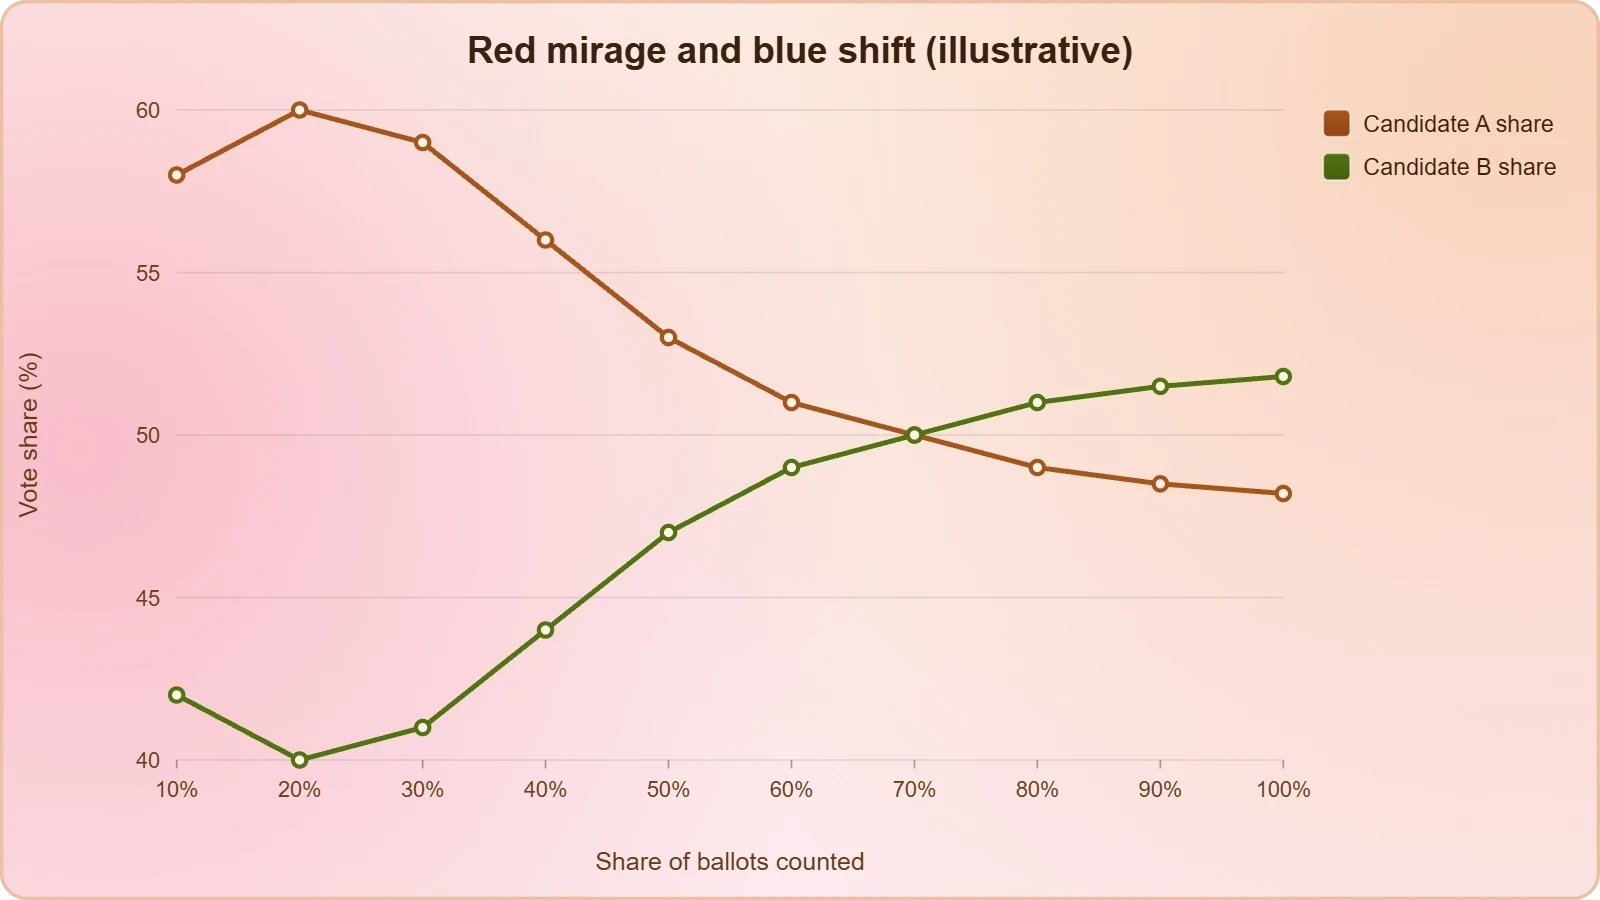
The geography of vote reporting is one of the most consequential and least understood variables in election analysis. Counties report at different speeds, and the order in which precincts report is rarely random. Rural areas with fewer ballots often count quickly, while dense urban jurisdictions may take hours or days, particularly when mail ballots require signature verification and processing. Analysts therefore build models that account for which precincts have reported and which remain outstanding, estimating the partisan composition of the unreported vote rather than simply extrapolating from the current tally.
This is where the concept of the "red mirage" and its counterpart, the "blue shift," enters public discourse. Early returns may favor one party because of the reporting order, only for the lead to narrow or reverse as later precincts report. Decision desks anticipate these patterns and explicitly model them, which is why a candidate may hold an apparent lead for hours without any call being made. The refusal to call a race during a misleading early lead is not indecision but a deliberate application of statistical caution.
Exit Polls and Their Evolving Role
Exit polling once served as the primary early indicator of electoral outcomes, but its role has narrowed considerably. Modern exit polls are conducted by a consortium of major news organizations and are designed less to project winners than to explain why voters chose as they did. The data on demographics, issue priorities, and approval ratings feeds post-election analysis and helps newsrooms interpret the meaning of a result. Using exit polls to call a race directly is now rare, and analysts treat them as corroborating evidence rather than primary proof.
The methodological challenges are substantial. Exit polls depend on accurate sampling of polling places, and they struggle to capture voters who cast mail ballots, a growing share of the electorate. Response bias, whereby certain voters are more willing to participate, can skew results. For these reasons, decision desks weight exit poll data cautiously, using it to validate or challenge the picture emerging from actual vote counts. When the two diverge sharply, analysts investigate rather than rush to a conclusion, treating the discrepancy as a signal that something requires explanation.
We Also Published
The Statistical Logic of Calling a Race
Beneath the public-facing drama lies a formal statistical problem: given a partial vote count and a model of the outstanding ballots, what is the probability that the current leader will ultimately prevail? Decision desks frame this as a threshold question. A race is called when the estimated probability of the trailing candidate overtaking the leader falls below a predetermined level, often expressed as a fraction of a percent. This is not a claim of absolute certainty but a judgment that the remaining uncertainty is small enough to be responsibly resolved in public.
The mathematics of this judgment can be expressed compactly. If ##V_L## represents the votes currently held by the leading candidate and ##V_T## those held by the trailing candidate, with ##R## outstanding ballots remaining, the trailing candidate can overtake only if the share of remaining votes won exceeds a threshold. That threshold can be written as:
When this required share exceeds the maximum plausible performance of the trailing candidate, given the partisan composition of the unreported precincts, the race is effectively decided. Analysts estimate that maximum plausible share using historical data on how similar precincts have voted, adjusted for turnout patterns and any known shifts in the political environment. The elegance of the approach lies in its transparency: the reasoning can be explained in plain language, and the assumptions can be scrutinized by outsiders.
Modeling the Unreported Vote
The hardest part of the analysis is estimating the composition of ballots that have not yet been counted. Analysts know which precincts have reported and which have not, and they know the historical partisan lean of each. By comparing the reported vote in a precinct to its expected performance, they can detect whether a candidate is overperforming or underperforming, and they can project that deviation onto the outstanding precincts. This is a form of ecological inference, and it requires careful handling because precincts are not homogeneous and turnout can vary unpredictably.
Mail ballots introduce a further complication. In many states, mail ballots are processed after in-person votes, and their partisan composition can differ systematically. Analysts therefore maintain separate models for in-person and mail ballots, tracking the reported share of each and projecting the remainder accordingly. The order in which these categories are counted varies by state and even by county, which is why the same national result can produce wildly different trajectories in different jurisdictions. A robust model must be flexible enough to accommodate these procedural variations without losing statistical rigor.
Thresholds, Confidence, and the Language of Certainty
The threshold at which a race is called is a matter of institutional policy rather than mathematical necessity. Different outlets set different bars, and those bars may be adjusted for the stakes of the contest. A presidential race may require a higher degree of confidence than a state legislative contest, simply because the consequences of error are greater. These thresholds are typically reviewed after each election cycle, incorporating lessons from any miscalls and advances in modeling technique. The result is a living methodology that evolves with experience.
The language used to communicate a call is calibrated to the underlying confidence. A "projection" signals a journalistic judgment based on evidence; a "call" carries similar weight; an "official result" is reserved for certification by electoral authorities. When a race is too close to call, outlets say so explicitly rather than hedging with vague language. This transparency is intended to preserve credibility: audiences are told not only what the desk believes but how strongly it believes it, allowing them to calibrate their own confidence accordingly.
The Competitive Pressure and Its Discontents
American election coverage is a competitive market, and the race to call results first is a genuine commercial incentive. A network that projects a winner minutes before its rivals gains a measurable advantage in audience attention, and that advantage translates into advertising revenue and reputational standing. This dynamic is not new; it dates back to the telegraph era, when wire services competed to transmit results faster than their rivals. What has changed is the speed of the underlying data and the scale of the audience watching the calls unfold in real time.
Yet competition carries inherent risks. The pressure to be first can tempt outlets to lower their evidentiary thresholds, and a single premature call can inflict damage that outweighs any short-term gain. The history of American election coverage includes several cautionary episodes in which networks projected winners before the evidence justified it, prompting internal reviews and methodological reforms. These episodes are instructive because they demonstrate that the safeguards are not abstract ideals but responses to concrete failures, each one leaving the system more cautious than before.
Historical Miscalls and Their Legacy
The most frequently cited example is the 2000 presidential election, when several networks initially projected Florida for one candidate before retracting the call as the vote margin narrowed. The episode exposed the fragility of projection models when the underlying vote is extremely close and the reporting order is misleading. It led to the creation of more rigorous decision-desk protocols, including the requirement that calls be based on actual vote counts rather than exit polls alone, and it permanently changed how networks communicate uncertainty to their audiences.
Subsequent cycles have produced smaller but still instructive errors, including premature calls in state and local races that were later reversed. Each incident has reinforced a culture of caution within decision desks, where analysts are trained to resist pressure from producers and to err on the side of withholding a call. The legacy of these miscalls is a system that is slower than it could be but more reliable than it once was, a trade-off that most outlets have accepted as the price of credibility.
Ethics, Transparency, and Public Trust
The ethical dimension of race calling extends beyond accuracy to transparency. Outlets that explain their methodology, publish their thresholds, and acknowledge uncertainty build a reservoir of trust that sustains them through contested moments. Conversely, outlets that treat projections as infallible or refuse to explain their reasoning invite suspicion, particularly in an era of heightened partisan distrust of media institutions. The decision to call a race is therefore not only a statistical act but a communicative one, and its legitimacy depends on the audience's willingness to accept the institution's authority.
This is why many outlets now publish detailed explanations of how they make calls, including the data sources they use, the thresholds they apply, and the checks they perform. Some maintain public-facing blogs or methodology pages that document their reasoning in real time. The goal is to demystify a process that can appear opaque, and to give audiences the tools to evaluate the calls they see. In a fragmented media environment, this transparency is one of the few mechanisms available for sustaining shared confidence in electoral outcomes.
- 01
- 02
- 03
- 04
Projection Versus Certification: A Crucial Distinction
The gap between a projected winner and a certified one is one of the most consequential distinctions in American electoral practice, and it is frequently blurred in public discussion. A projection is a journalistic judgment, however rigorous, that a particular candidate will win based on available evidence. Certification is a legal act performed by state officials after canvassing, recounts, and audits are complete. The two can diverge, and when they do, the divergence becomes the subject of litigation, political contestation, and intense public scrutiny.
This distinction matters because projections carry no legal weight. A candidate projected as the winner has not been elected in any formal sense until the state certifies the result. In practice, projections almost always align with eventual certifications, which is why they are treated as reliable. But the exceptions, however rare, demonstrate why the language of projection is carefully chosen. Outlets that conflate the two risk misleading their audiences and undermining the very authority their projections depend upon.
Recounts, Audits, and Contested Outcomes
When a race is close enough, state law may trigger an automatic recount or permit a candidate to request one. Recounts can change outcomes, though large reversals are rare. Audits, which verify that voting equipment recorded ballots accurately, provide a separate layer of assurance. Decision desks monitor these processes closely, and a projection may be revisited if a recount produces a different result. The willingness to revise a call in light of new evidence is a mark of methodological integrity rather than weakness.
Contested outcomes present a harder challenge. When a candidate refuses to concede or alleges fraud without evidence, the projection stands as a journalistic judgment while the legal process unfolds separately. Outlets must navigate this terrain carefully, reporting on the dispute without amplifying unfounded claims. The decision desk's role in such moments is to maintain the integrity of its call while acknowledging that the formal process has not concluded, a balancing act that requires both statistical confidence and editorial restraint.
International Comparisons
The American practice of newsroom-declared winners is unusual internationally. In many countries, the authority to announce results rests with an electoral commission, and media outlets report those announcements rather than making independent projections. The American model reflects a particular historical context, including a decentralized election administration and a strong tradition of independent journalism. Comparing the two approaches illuminates the trade-offs involved: the American system offers speed and analytical depth, while the commission model offers a single authoritative voice.
Neither approach is immune to error or controversy. Commission-announced results can be delayed or disputed, and media projections can be premature. What matters is the transparency of the process and the robustness of the checks. The American system compensates for its decentralized authority with elaborate methodological safeguards, while commission-based systems rely on legal authority rather than journalistic judgment. Understanding these differences helps observers interpret election coverage across different national contexts.
Technology, Speed, and the Future of Race Calling
The technological infrastructure underpinning modern race calls has transformed dramatically over the past two decades. Where analysts once relied on telephone reports and manual tabulation, they now draw on automated data feeds, real-time dashboards, and machine-learning models that can process precinct-level returns as they arrive. This acceleration has compressed the interval between the closing of polls and the first calls, particularly in races where the outcome is not close. Yet the underlying judgment remains human, and the technology serves the analysts rather than replacing them.
The next frontier involves integrating richer data sources, including voter-file records, early-vote tallies, and geospatial turnout models. These tools promise greater precision but also introduce new risks, including over-reliance on models that may not capture unprecedented events. The discipline of the decision desk lies in balancing technological capability with methodological humility, recognizing that no model can fully anticipate every contingency. The most sophisticated operations are those that use technology to expand their evidentiary base while preserving space for human judgment.
Automation and the Human Firewall
Automation has made it possible to ingest and process vote totals at a speed no human team could match, but it has not eliminated the need for human oversight. Analysts review automated outputs, investigate anomalies, and make the final call. This human firewall is essential because automated systems can propagate errors, particularly when data feeds are corrupted or mislabeled. The most robust operations build in redundancy, cross-checking automated results against manual reports and flagging discrepancies for review before any call is transmitted.
The balance between automation and human judgment is a recurring theme in the design of decision desks. Too much automation risks error propagation; too little forfeits the speed advantage that competition rewards. The mature approach treats automation as a tool for expanding analytical capacity while reserving the final judgment for trained analysts who can weigh context, recognize anomalies, and exercise discretion. This division of labor reflects a broader principle: technology should augment human judgment, not supplant it.
Rebuilding Confidence in a Polarized Era
The most significant challenge facing race calling today is not technological but political. In an environment of heightened partisan distrust, projections are increasingly treated as partisan acts rather than neutral analysis. Outlets must therefore work harder to demonstrate their independence, publishing methodologies, explaining reasoning, and acknowledging uncertainty. The goal is not to persuade the skeptical but to provide a transparent record that can withstand scrutiny. Institutions that succeed in this effort will retain the authority to call races; those that fail may find their projections dismissed regardless of accuracy.
Rebuilding confidence also requires engagement with the public beyond election night. Educational initiatives that explain how projections work, why they sometimes take time, and how they differ from certification can help audiences interpret what they see. Some outlets have invested in such efforts, producing explainer content and hosting public discussions. These investments are unlikely to eliminate distrust entirely, but they can create a baseline of understanding that makes projections more legible and less susceptible to misrepresentation.
What the Machinery Reveals About Democracy
The elaborate apparatus of race calling is, in the end, a reflection of something deeper: the American commitment to decentralized electoral administration paired with a free press that assumes the responsibility of interpretation. No single authority announces results; instead, thousands of local officials count ballots while a handful of newsrooms synthesize those counts into a coherent national picture. This arrangement is messy, competitive, and occasionally error-prone, but it has proven remarkably durable because it distributes both authority and accountability across multiple institutions.
Understanding how calls are made also illuminates the fragility of public confidence. A projection is only as credible as the institution behind it, and that credibility depends on transparency, methodological rigor, and a willingness to correct mistakes. When these qualities are present, projections serve as a public good, helping citizens understand outcomes without waiting days or weeks for certification. When they are absent, projections become another front in the partisan contest over electoral legitimacy, and the machinery that once commanded broad trust begins to lose its authority.
The lesson for observers is to treat race calls with the same calibrated confidence that decision desks themselves apply. A projection is a strong signal, not a legal fact; it deserves attention but not blind acceptance. The institutions that make these calls have earned a measure of trust through decades of practice, but that trust is contingent on continued transparency and rigor. Citizens who understand the machinery are better equipped to evaluate its outputs, and a public that understands the process is more resilient against those who would exploit its uncertainties for political advantage.
From our network :
- University Language Proficiency Exams: Why Institutional Tests Demand Different Preparation Than IELTS and TOEFLDiscover why university-specific language proficiency examinations differ fundamentally from IELTS and TOEFL, and learn strategic preparation approaches for institutional assessment success.
- CISA’s Ten-Advisory Wave: Why Generic Patching Fails in OT and How to Build Product-Specific PlaybooksCISA released ten ICS advisories in one week, exposing critical infrastructure risks. Generic patching fails in OT. Learn to build product-specific remediation playbooks.
- Mobile Learning and VR in English: What Global Evidence Reveals About Effective Language TechnologyA systematic review across 14 countries reveals which language-learning technologies genuinely work. Mobile learning, AI, and VR show measurable benefits when pedagogically integrated. This evidence-based guide helps educators and learners select technology that delivers real return on investment.
- Live Online English Classes for Kids: Do They Actually Reduce Anxiety?A ten-week study reveals that synchronous online English classes can significantly reduce child language anxiety while improving listening and reading skills. Discover what makes these programs effective and how parents can select the right one.
- Committed Mediterranean Precipitation Decline: Why Emissions Cuts Alone Cannot Restore Winter RainsNew NOAA research reveals that Mediterranean winter rains may decline irreversibly even with emissions cuts. Explore the science of committed climate change and regional impacts.
- The Hidden Cost of AI Convenience: Why Over-Permissioned Agents Are a Security Time BombDiscover why AI agents with excessive permissions create dangerous single points of failure, and learn how implementing least privilege principles can protect your organization from exploitation.
- The Final Descent: How ESA Retired the Legendary Cluster Constellation After 24 Years of Space Weather ScienceAfter 24 years mapping Earth’s magnetosphere, ESA’s Cluster mission concluded with a precisely controlled reentry over the South Pacific. This analysis explores the scientific legacy, engineering decisions, and debris mitigation principles behind one of space exploration’s most responsible retirements.
- How AI Agents Will Change the Way We Manage Personal FinancesExplore how AI agents are transforming personal finance through automated budgeting, bill payment, and investment management, while examining the critical security protocols and governance frameworks required for safe deployment.
- Forbidden Matrix Patterns and Visible Lattice Points: A Geometric DictionaryExplore how multidimensional 0–1 matrices encode geometric truths, linking forbidden patterns to visible lattice points and hypergraph theory, with applications in combinatorics and computational geometry.
RESOURCES
- How US news organizations will make midterm race calls | Reutersreuters.com2 hours ago ... While most of the major TV networks use the same AP vote count tabulation to make their calls, the ones…
- Explainer-How US News Organizations Will Make Midterm Race Callsusnews.com3 days ago ... While most of the major TV networks all use the same AP vote count tabulation to make their calls, the…
- Midterm elections 2026: how are votes counted and when will we ...theguardian.com4 hours ago ... Midterm elections 2026: how are votes counted and when will we know the results? · How are votes counted? ·…
- When will we know 2026 midterm election results? It may take ... - PBSpbs.org3 days ago ... In past elections, elected leaders, candidates and social media users have spread falsehoods that “late night” arrivals of “ballot dumps”…
- How Media Outlets Call Races from Unofficial Election Resultsbipartisanpolicy.orgFeb 20, 2026 ... ... National Election Pool aggregate election data and call elections. ... know them and let them know what they can…
- What Are Midterm Elections, Why Are They Important?tr.usembassy.govNov 8, 2022 ... U.S. presidential elections are big news worldwide every four years. But what happens in the midterm elections — so called…
- Why We Might Not Know Election Results Right Awaybipartisanpolicy.orgFeb 20, 2026 ... The 2026 midterm elections will determine control of Congress for ... Media outlets and data aggregators call races based on…
- The EAC Calls on Americans to Become Poll Workers Ahead of ...eac.govJan 27, 2026 ... With the 2026 midterm elections beginning in early March, the U.S. Election Assistance Commission (EAC) is urging Americans to sign…
- Why it'll take a while to know who won in some midterm races - NPRnpr.orgOct 19, 2026 ... (NPR relies on The Associated Press for its race calls.) Those ... know which party will control the U.S. Senate…
- The Trump Administration Has No Legal Authority To Invoke ...americanprogress.orgMar 3, 2026 ... ... midterm elections. President Donald Trump denied that he is ... Just as importantly, media outlets have reported that the…
- Five Things to Know About the Midtermscfr.orgOct 13, 2026 ... Even if you think that as many as nine Senate seats are still too close to call, that means that…
- Cook Political Report | Non-Partisan Political Analysis for US ...cookpolitical.comThe Cook Political Report with Amy Walter is an independent, non-partisan newsletter that analyzes state, federal and presidential elections, and American ...
- Logic & Accuracy Advisory & General Election Coverage Opportunitieskingcounty.govOct 7, 2026 ... For the fastest response, email the Elections Media inbox at elections.media@kingcounty.gov or give us a call at 206-477-4111. You can…
- Frequently Asked Questions | Alabama Secretary of Statesos.alabama.govYou can find information about upcoming elections in your area here. I turned in a voter registration application. Am I registered to vote? Just…
- Vote by mail in U.S. - Minnesota Secretary Of Statesos.mn.gov2026 Absentee Voting Dates. Ballots are available starting 46 days before an election (except for March Township elections, which are available 30 days before ...
- 01
- 02
- 03
- 04
- 05
- 06
- 07
- 08
0 Comments